Share this article


Accelerating security solutions for small businesses Tagore offers strategic services to small businesses. | A partnership that can scale Tagore prioritized finding a managed compliance partner with an established product, dedicated support team, and rapid release rate. | Standing out from competitors Tagore's partnership with Vanta enhances its strategic focus and deepens client value, creating differentiation in a competitive market. |
This blog is part of our Trustcraft series, in which we dig into Vanta’s approach to building with AI. Read the first blog in this series to learn more about how we define Trustcraft.
A growing number of internal teams at Vanta are building out functionality to improve the coverage of the Vanta Agent. Tens of new tools might be released each week, increasing not only the usefulness of the agent but also the number of tokens used in each request and the number of decisions for the agent to make.
At the time of writing this blog post, our agent has over 280 tools, spanning tens of product areas, taking up over 75k tokens before the LLM even starts its completion.
That prefix is sent on every call. A cache hit makes it much cheaper to process, but it still consumes context and cache-read input. On top of that, the agent has to consider hundreds of tools for every decision it makes, which can inhibit output quality. Given our expanding toolset, showing the agent all the tools all the time was no longer a viable option.
Tool discovery looked like it should make our agent slower. Loading tools dynamically changes an early part of the prompt, which invalidates cache and can lead to inefficiencies. We shipped it anyway - and latency, cost, and quality improved.
A model needs to process input tokens before generating a response. This phase, called prefill, builds the attention state the model uses during token generation.
In a transformer architecture, processing a given token requires attending to the tokens before it. This means that each additional token must attend to a longer preceding prefix, causing the total attention work during prefill to grow quadratically with prompt length.
This is especially relevant for the agent use case. An agent may make many LLM calls, each of which processes the system prompt, tools, and an increasing number of messages.
Enter prompt caching. During prefill, the provider builds a cache with the intermediate attention state of tokens it has already processed. If a conversation is append-only, the model can often reuse the existing prefix cache, and only has to prefill the additional suffix. This drastically reduces the latency and cost of these LLM calls.
Details vary by provider, but when a cache is hit, you save on inference costs. For example, Gemini 3.7 Flash currently prices standard cached input at $0.075 per million tokens, compared with $0.75 per million uncached input tokens.
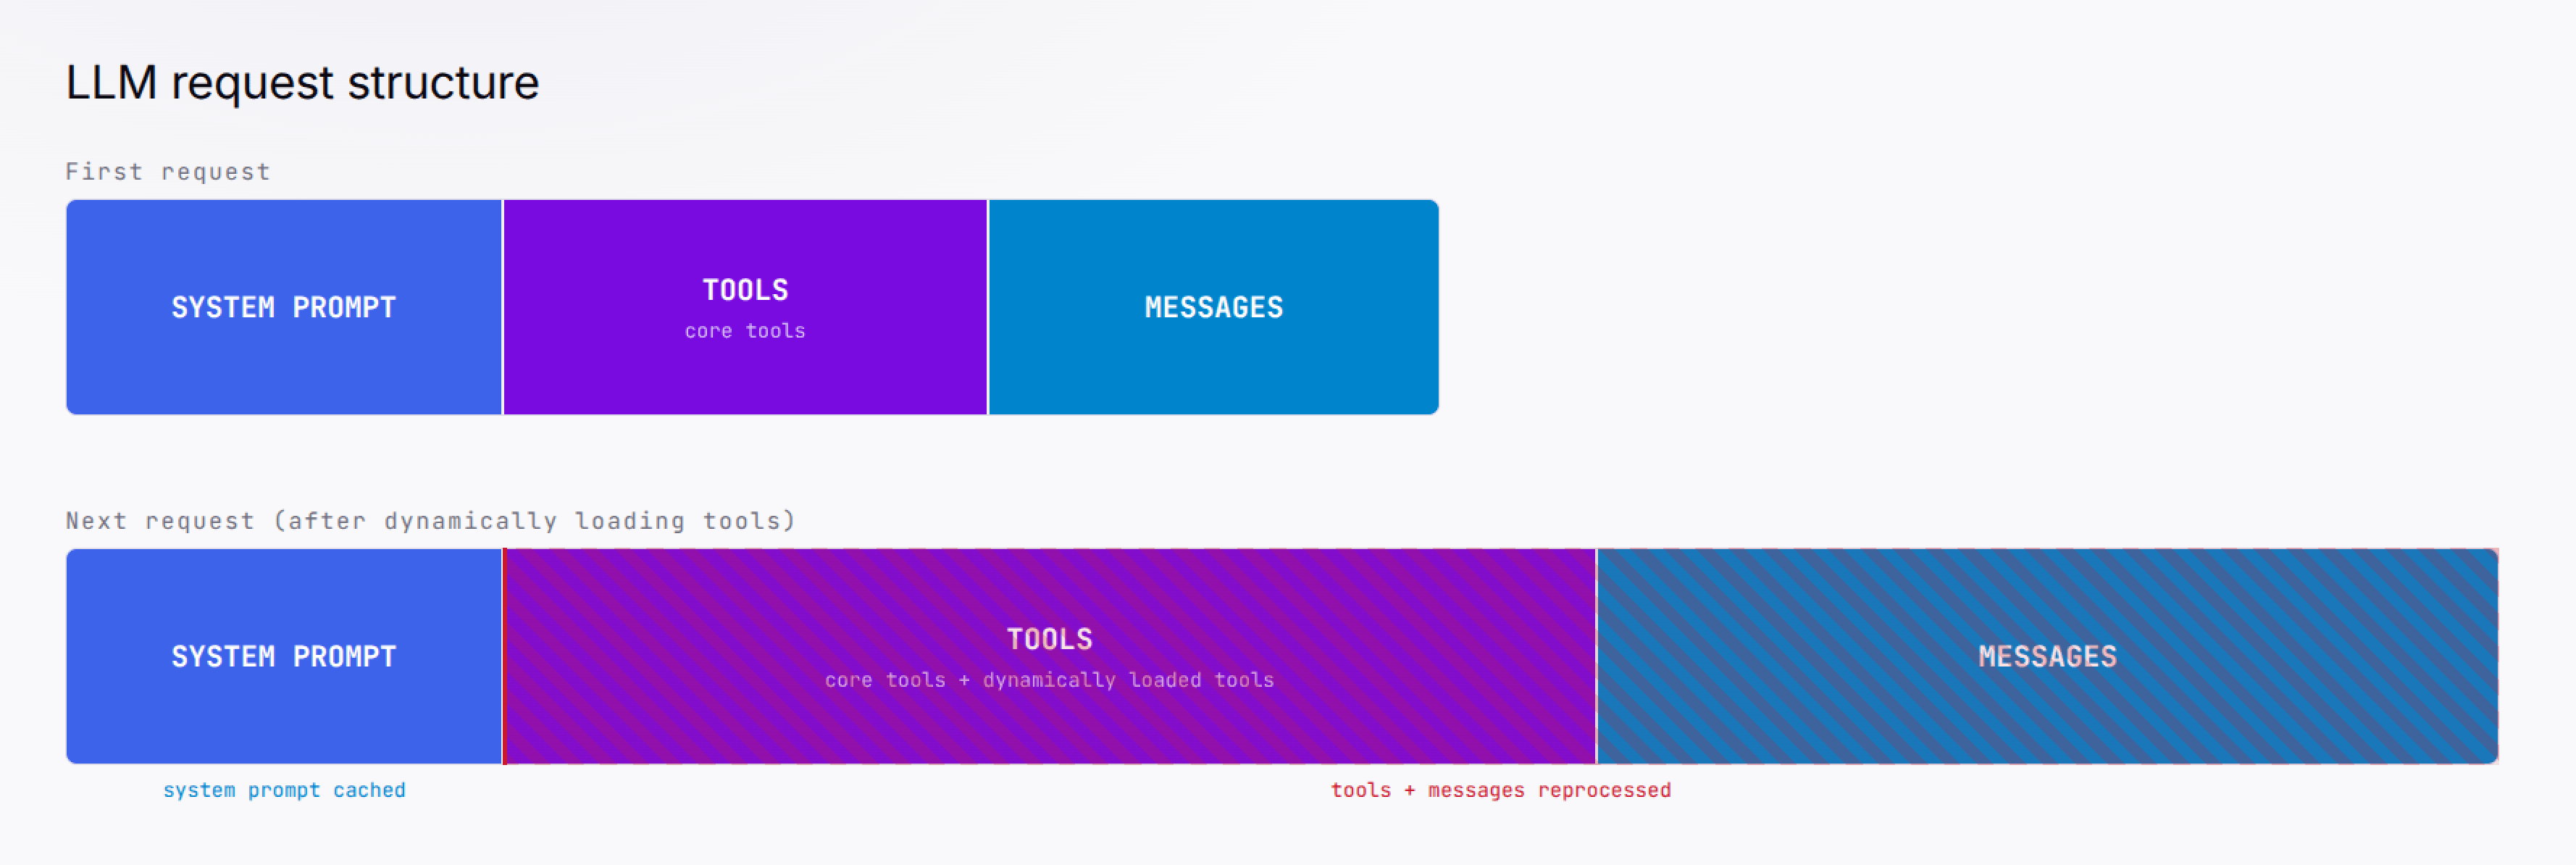
Another thing to note is that model providers often serialize the system prompt and tool definitions at the beginning of the prompt, with messages following afterwards. A change near the start of the request breaks reuse after the first changed token. In a conventional tool payload, adding a tool can force the provider to re-process the entire conversation that follows it. This is an important consequence for later.
If you want a more in-depth read on prompt caching, check out this blog post that I found helpful.
As a result of the quick and consistent increase in tools, we decided to look into alternatives. Nathan Heskia built out a hack day project for tool discovery, which we used as the starting point for our experiments.
At its most basic form, tool discovery restricts the number of tools the agent sees and allows it to expand its toolset dynamically, rather than showing the agent all available tools at once. Given the prompt caching learnings from above, this comes with an obvious downside: Dynamically loading tools at the beginning of the context window will invalidate most of the cache whenever tools are added.
Some newer OpenAI and Anthropic models have native deferred tool loading functionality that allow you to dynamically add tools without invalidating the cache. They do so by appending tool definitions rather than inserting them at the beginning of the request. However, as of writing, Gemini and many open-source models don’t have a similar mechanism for doing so. We use Gemini and wanted to keep our harness model-agnostic, so we thought through solutions with this constraint in mind.
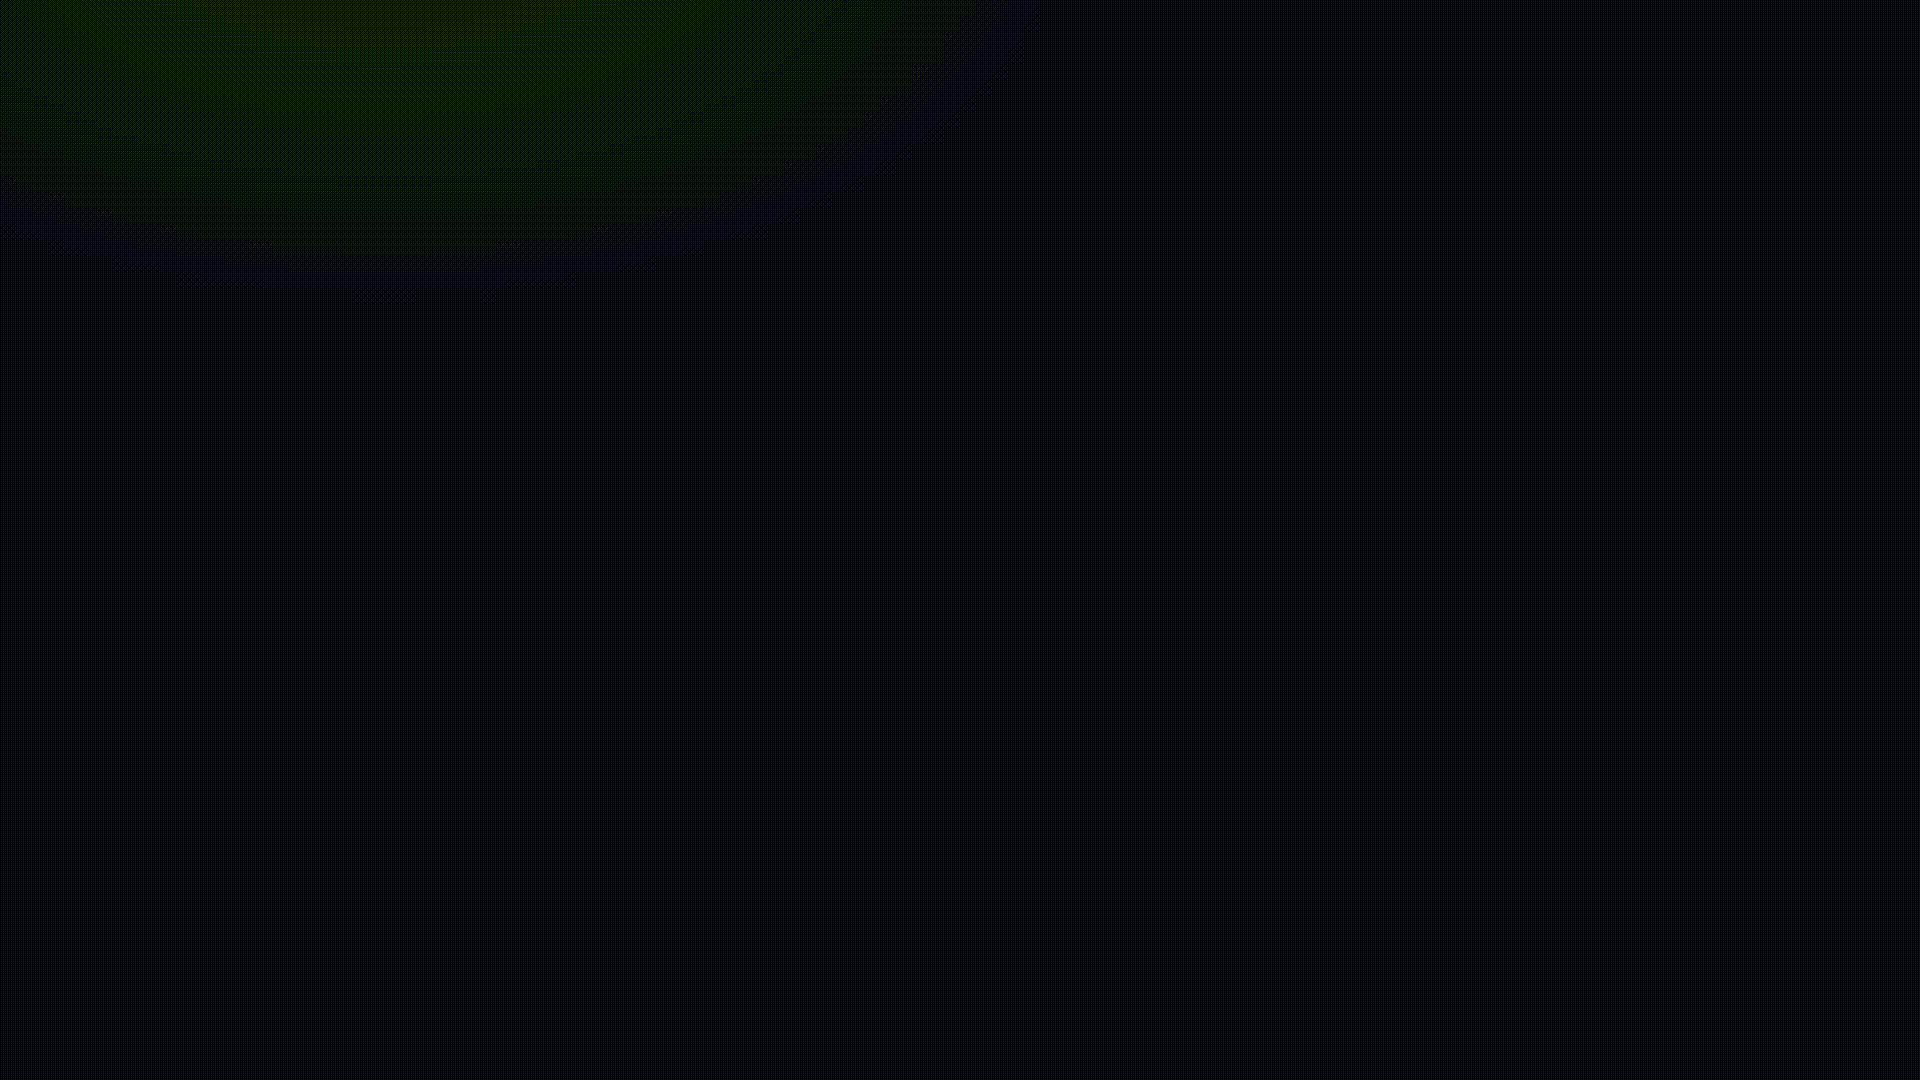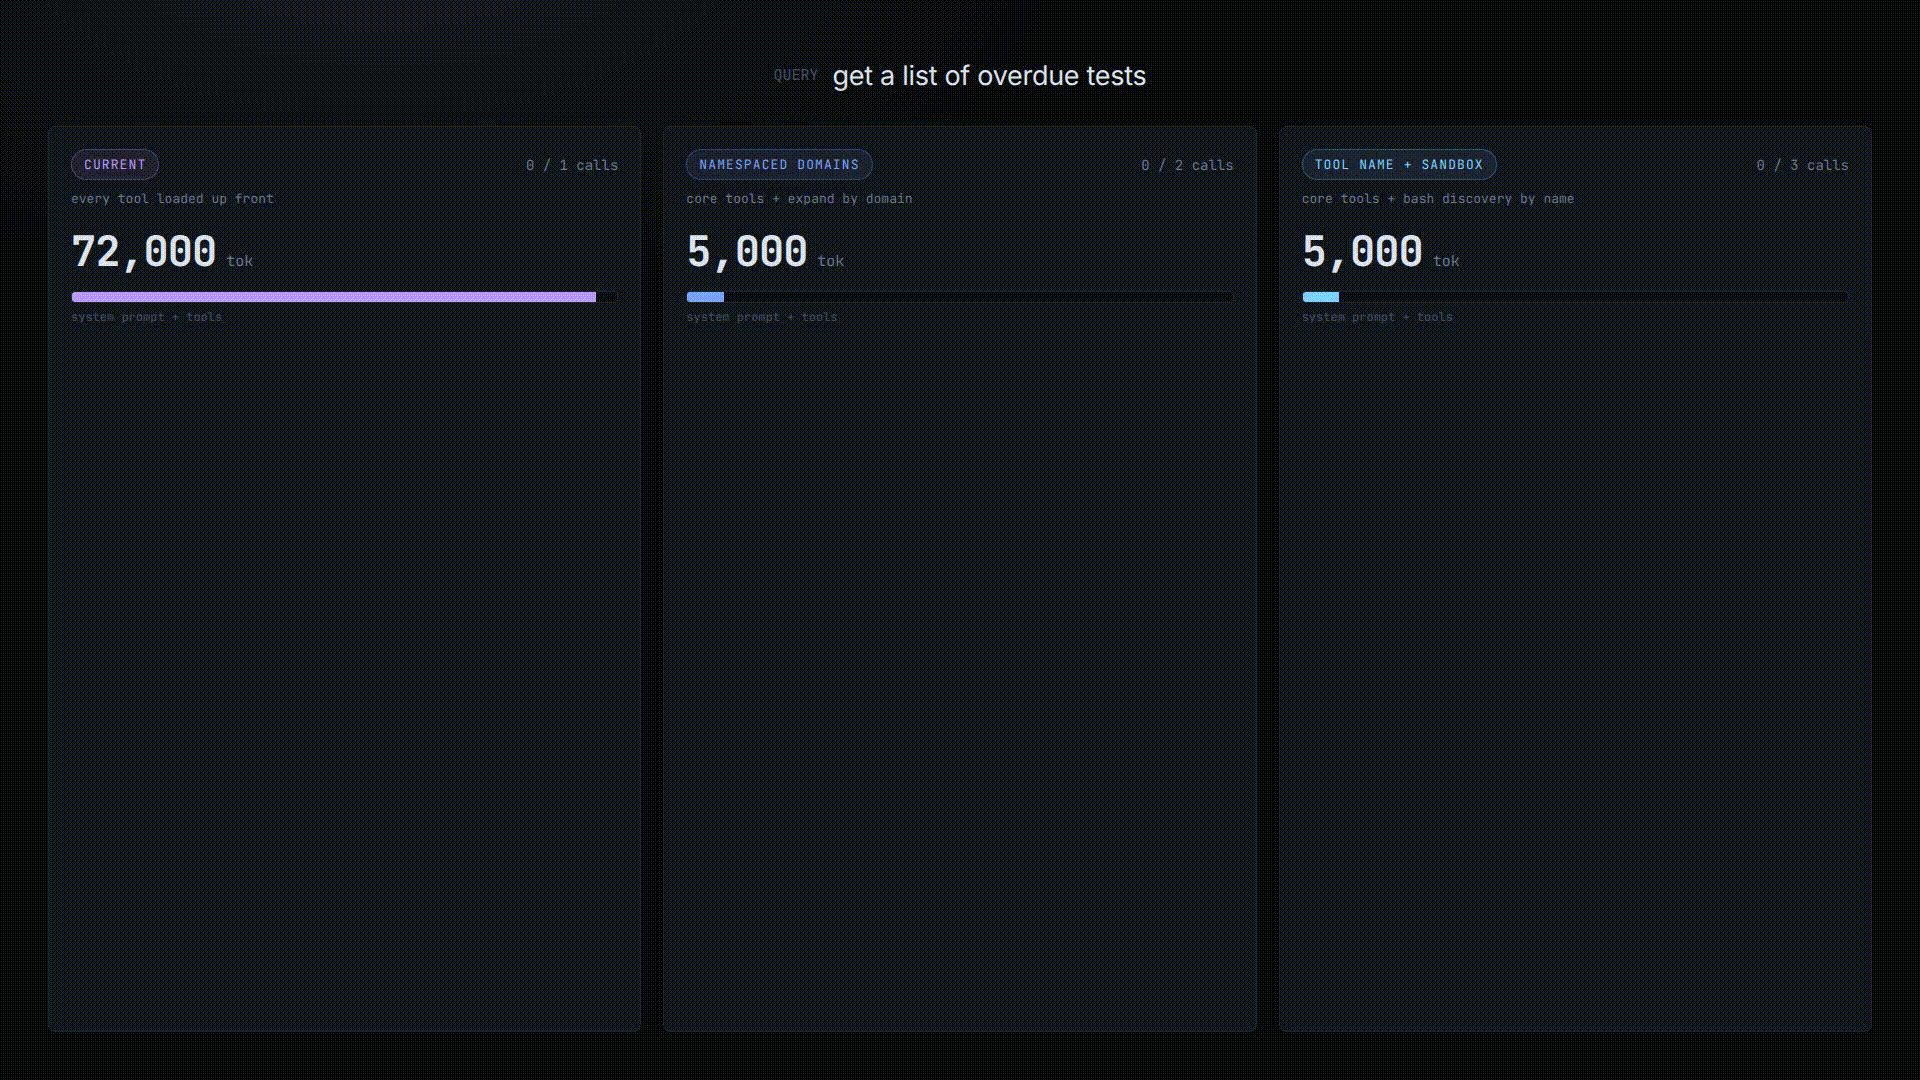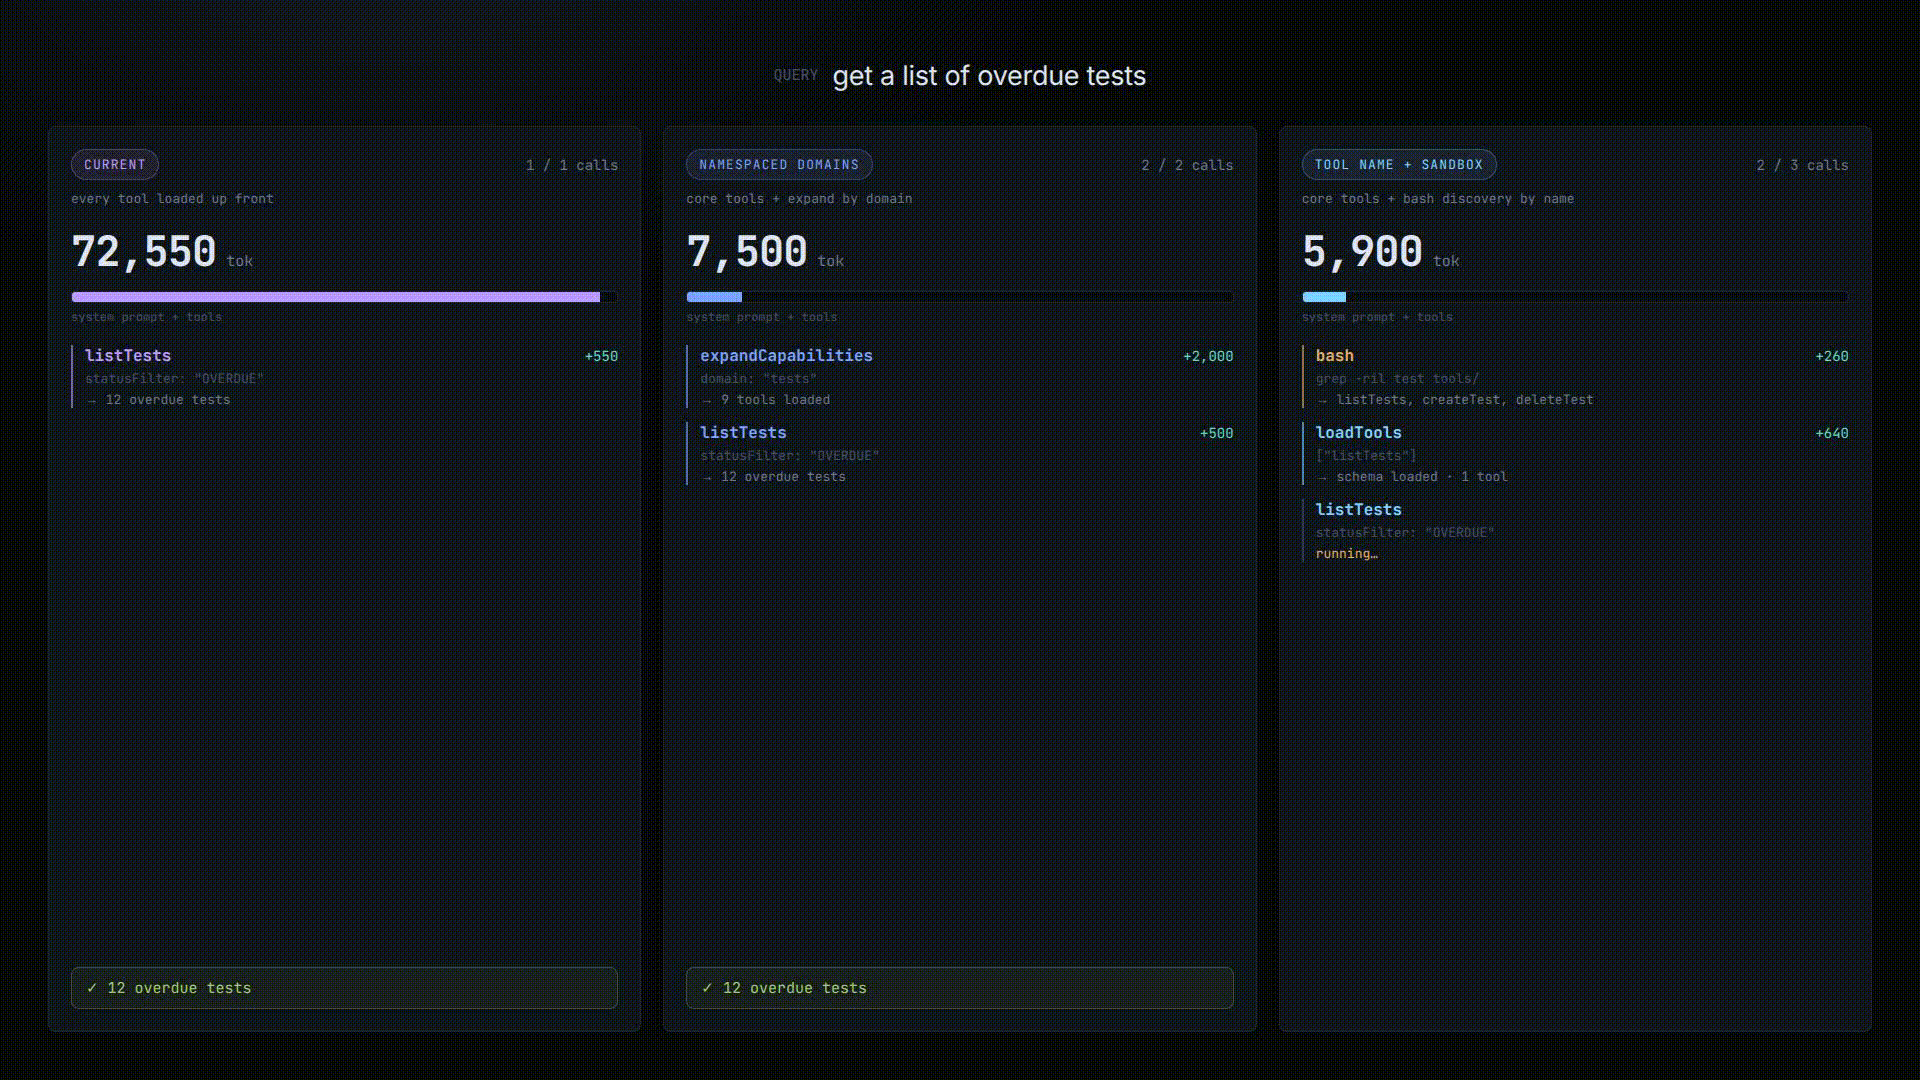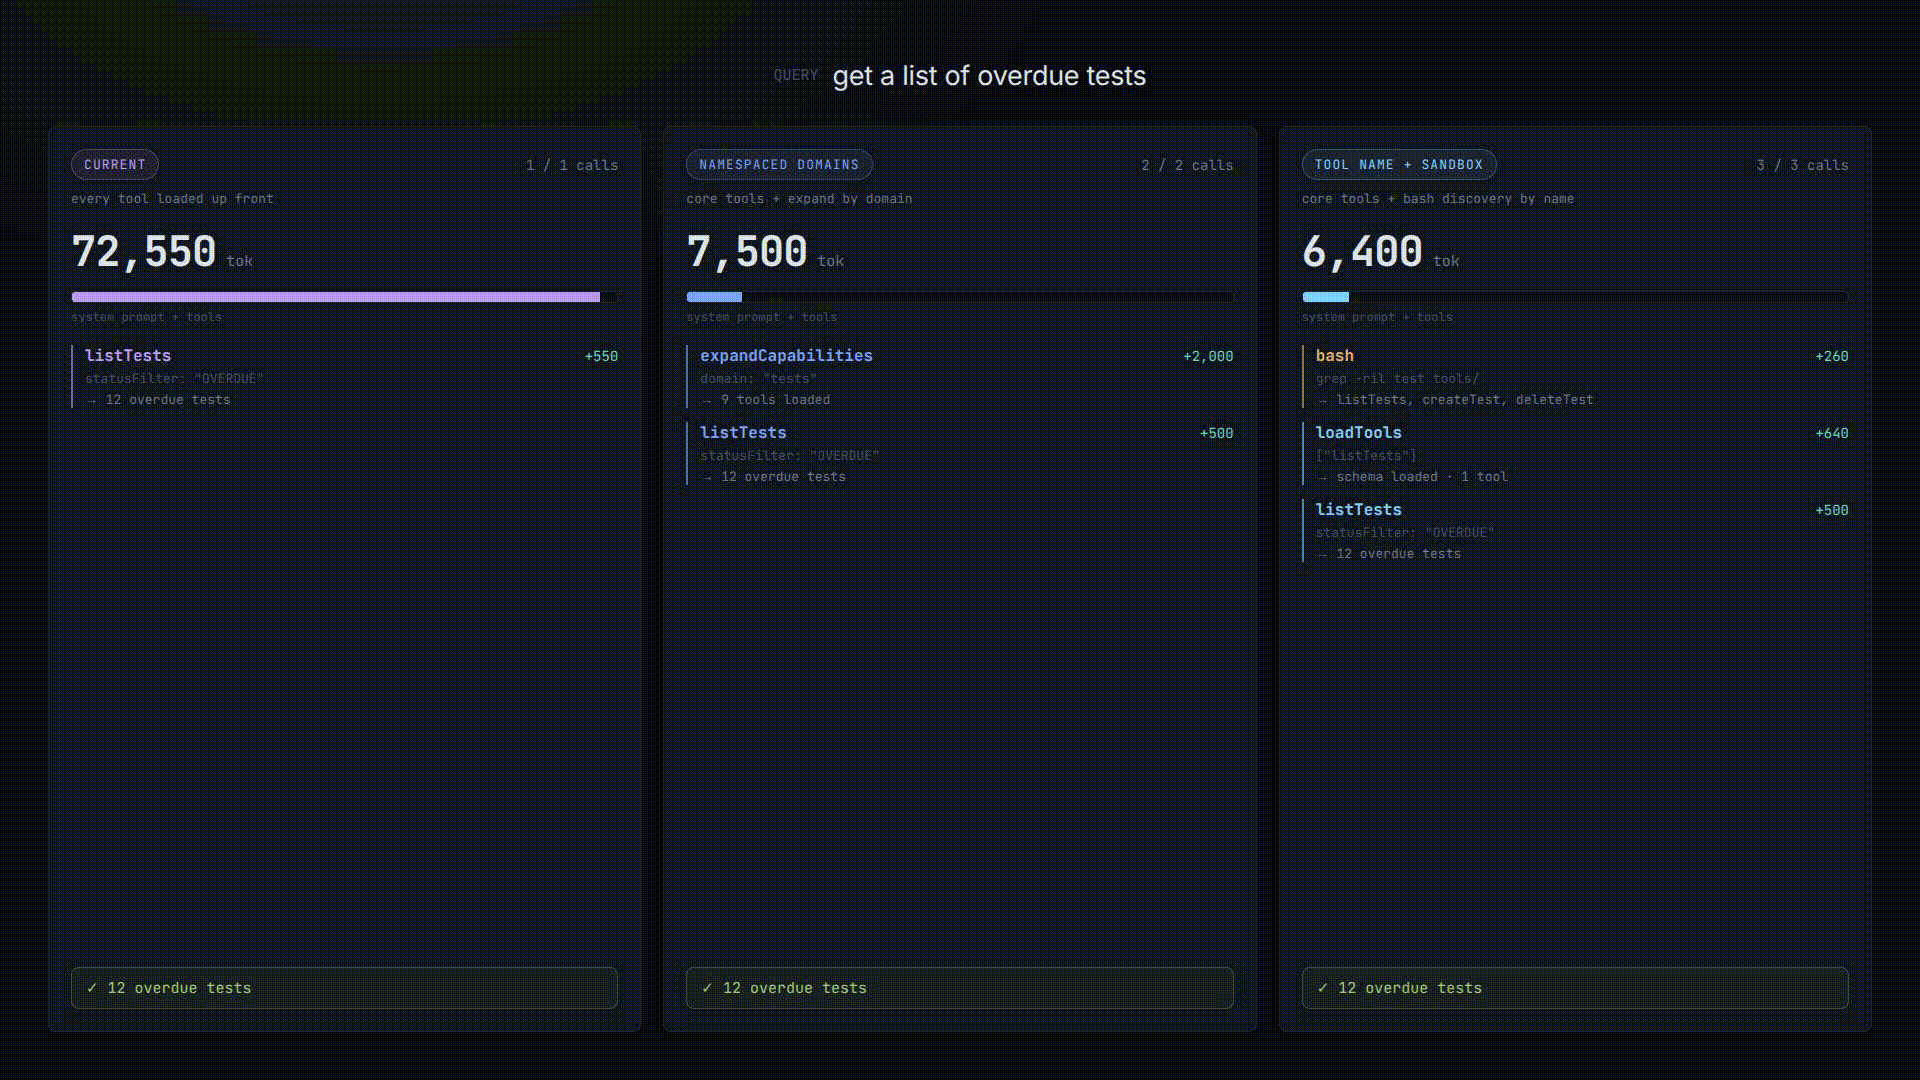
We experimented with a couple of architectures:
To narrow our selection, we ran each solution, along with our current state of the world, through a series of offline evals and local testing. As expected, our experiments showed a drop in cache-hit rate compared to the current architecture.
However, the cache invalidation didn’t harm our latency or quality metrics. In fact, we saw that the new experiments made queries much quicker and improved agent quality, all while decreasing cost and token usage.
Testing complex queries on a large domain locally, we found that the improvements were even more pronounced. Even multi-turn conversations that changed topics every turn showed good results for our solutions, with the improved agent decision making offsetting any cache invalidation. Ultimately, the domain-based tool discovery won out.
There’s one core consideration we kept in mind when building out domain-based tool discovery: Changing the toolset will invalidate cache for all messages that follow. In other words, expanding tools at the beginning of a conversation is relatively cheap. Doing so afterwards in a long-running conversation is much, much more costly.
That constraint shaped our decision-making.
We dug into the data and uncovered a usage pattern that informed our architecture: Only 3% of conversations switched topics. This meant that an effective call to expand tool capabilities in the beginning of a conversation usually output sufficient tools for the entire conversation. Most likely, we would only invalidate cache at the start of the conversation when it was cheapest.
This meant that we were ok with over-fetching but not under-fetching categories. Optimizing for one early, broad expansion allows the agent to pay the cost early. We deliberately tolerate loading extra domains because the cost is low—each additional domain will add on the order of thousands of tokens at most. False negatives are worse, as they can produce an inaccurate answer based on an incomplete toolset or require expansion that rewrites a much longer cached prefix.
Once a domain was loaded, we kept its tools available for the rest of the conversation. This kept the request prefix stable and ensured the model never saw a tool in an earlier turn that had disappeared from its current callable set.
You might also remember that Vanta has a very wide surface, with tens of product areas. Because a user is usually staying on-topic, the agent only really needs a scoped subset of tools for the relevant product areas. That made domain-based tool discovery a natural fit.
We made a deliberate trade-off to break caching early in exchange for a smaller, focused toolset. Our observed conversation patterns and Vanta’s broad, domain-oriented product gave us confidence that the experiment results would transfer well to production.
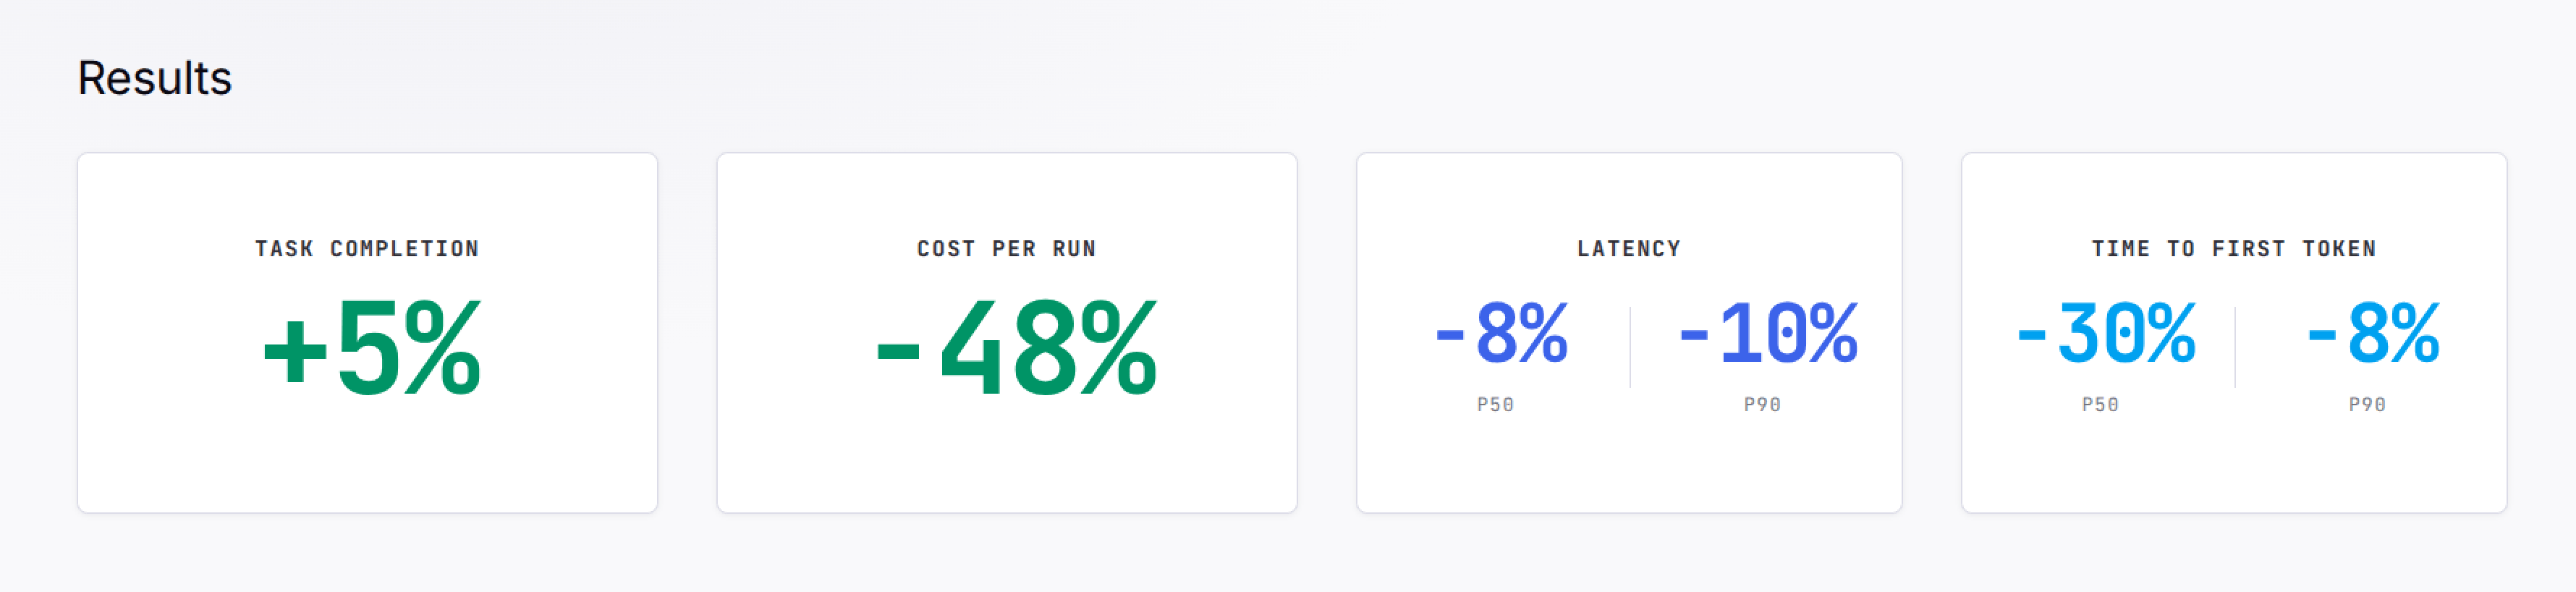
The results of the tool discovery on production were stronger than the offline evals predicted. Cache-hit rate dropped, while task completion rate increased and latency and cost declined. Quality (measured by task completion rate) increased 5% relative to the prior solution, cost per run declined 48%, and P50/P90/P99 latency dropped by 8%/10%/15% respectively. P50/P90/P99 TTFT saw similar decreases of 30%/8%/15%.
Cache-hit rate declined because the first expansion changed an early prompt prefix. However, the agent generally expanded once near the beginning of the conversation, then reused the smaller, stable toolset for remaining turns. Cache invalidation was pushed to the place where it was the least harmful.
We didn’t only optimize for cache-hit rates. With our usage patterns and large number of tools, we made the deliberate decision to invalidate cache early in the conversation in exchange for a smaller stable toolset. That trade-off has paid dividends for us.
The Vanta engineering team is growing. See open roles.

Learn how to scale, manage, and optimize alongside your business goals.